Free Quiz
Write for Us
Learn Artificial Intelligence and Machine Learning
  • Artificial Intelligence
  • Data Science
    • Language R
    • Deep Learning
    • Tableau
  • Machine Learning
  • Python
  • Blockchain
  • Crypto
  • Big Data
  • NFT
  • Technology
  • Interview Questions
  • Others
    • News
    • Startups
    • Books
  • Artificial Intelligence
  • Data Science
    • Language R
    • Deep Learning
    • Tableau
  • Machine Learning
  • Python
  • Blockchain
  • Crypto
  • Big Data
  • NFT
  • Technology
  • Interview Questions
  • Others
    • News
    • Startups
    • Books
Learn Artificial Intelligence and Machine Learning
No Result
View All Result

Home » Toward a latest framework to accelerate large language model inference

Toward a latest framework to accelerate large language model inference

Tarun Khanna by Tarun Khanna
August 8, 2025
in Artificial Intelligence, Machine Learning
Reading Time: 3 mins read
0
Toward a latest framework to accelerate large language model inference

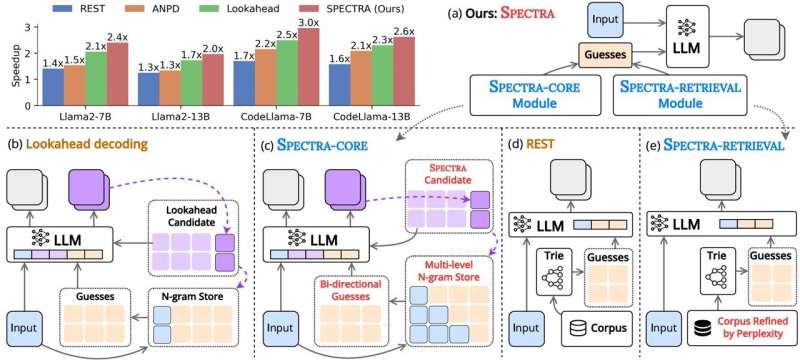
Schematic diagram of SPECTRA and other existing training-free approaches. Photo Credit: https://techxplore.com/

Share on FacebookShare on TwitterShare on LinkedInShare on WhatsApp

High-quality output at low latency is a crucial necessity while the usage of large language models (LLMs), specifically in real-world situations, including chatbots dealing with clients, or the AI code assistants used by thousands and thousands of users daily.

Currently, LLMs use a framework referred to as autoregressive decoding, wherein text is generated one token at a time, and the preceding text is used to generate the next series. However, this is honestly inefficient, because for longer sequences, the time to generate responses will increase linearly.

To cope with this trouble, researchers are extensively exploring the use of theoretic decoding that follows a “guess and verify” framework. In this approach, a specifically trained smaller LLM guesses more than one text tokens in lend, that is concurrently proven by the original LLM, mostly decreasing the response generation time.

Also Read:

Google opens up latest AI models to 200 European researchers

AI agents develop their very own ‘artificial natural language’ to communicate about complex data

TikTok CEO Predicts Major AI Scientific Breakthroughs Within 3-Years

Microsoft Introduces Maia 300 AI Chip to Decrease Nvidia Dependence

But these approaches need extra model training and considerable computational sources. While researchers have taken into consideration training-free theoretic model in parallel, the speedup advantage in those tactics remains restrained due to a decreased quality of their theoretic guesses.

To cope with those gaps within the field, Professor Nguyen Le Minh and his doctoral students, Nguyen-Khang Le and Dinh-Truong Do, from the Japan Advanced Institute of Science and Technology (JAIST) currently advanced a new speculative decoding framework known as SPECTRA and verified expanded text generation speed without any need for additional training.

“The framework includes 2 main components: a core module (SPECTRA-CORE), which integrates seamlessly into LLMs in a plug-and-play manner, and an optional retrieval module (SPECTRA-RETRIEVAL) that further complements overall performance,” explains Prof. Nguyen. The team’s findings were presented at the 63rd Annual Meeting of the Association for Computational Linguistics (ACL 2025) by Dinh-Truong Truong and are posted in the conference proceedings.

SPECTRA-CORE, the core module, generates high quality guesses by usage of the text distribution pattern anticipated by the LLM, enhancing speculative decoding. In this smart system, dictionaries holding distinctive sizes of word sequences (N-grams) can be searched bidirectionally (forward and backward) to are expecting word mixtures, guessing phrases of various lengths fast and more precisely. Additionally, SPECTRA continues optimizing the N-gram dictionaries by continuously updating them with new word combinations, ensuring sturdy text coverage.

To speed things up further, the retrieval module, SPECTRA-RETRIEVAL, is incorporated into SPECTRA-CORE. Existing procedures that use external resources to retrieve information and generate guesses in speculative decoding often struggle to combine with different decoding frameworks as the search time exceeds speedup outcomes.

In contrast, SPECTRA-RETRIEVAL filters a large dataset of texts and continues only the parts which might be easy for the target LLM to expect based on perplexity scores. This, in turn, ensures that only high quality, applicable facts is used for training or fine-tuning the model, permitting seamless integration with SPECTRA-CORE.

In their observe, the team examined SPECTRA on 6 tasks, such as multi-turn conversations, code generation, and mathematical reasoning, across three LLM households—Llama 2, Llama 3, and CodeLlama. SPECTRA achieved 4x speedup accumulate and was able to outperform today’s non-training speculative deciphering techniques, drastically REST, ANPD, and Lookahead.

While the overall model a architecture and dataset traits determined the speedup gains of speculative decoding strategies, SPECTRA showed responsibility throughout a range of models and datasets, constantly accelerating speedup ratios.

“By incorporating our plug-and-play SPECTRA-CORE module—which leverages multi-level N-gram storage and bidirectional search—with the refined SPECTRA-RETRIEVAL module that selects high quality external cues through perplexity-primarily based filtering, we were able to achieve substantial speedups (as much as 4.08×) across diverse tasks and model architectures even as retaining the original model’s output quality,” states Prof. Nguyen.

By lowering the response generation time without wanting to retrain LLMs, SPECTRA offers a practical solution for industrial and research systems that use LLMs and could thoroughly result in stepped forward accessibility and sustainability of high-performance AIs in the long-time period.
ShareTweetShareSend
Previous Post

Investor Loses $3M in Crypto Phishing Scam After Signing Malicious Transaction

Next Post

NVIDIA recent: Blackwell GPU and software updates

Tarun Khanna

Tarun Khanna

Founder DeepTech Bytes - Data Scientist | Author | IT Consultant
Tarun Khanna is a versatile and accomplished Data Scientist, with expertise in IT Consultancy as well as Specialization in Software Development and Digital Marketing Solutions.

Related Posts

Inside Mark Zuckerberg’s decision to pull the trigger on Meta’s AI agent
Artificial Intelligence

Inside Mark Zuckerberg’s decision to pull the trigger on Meta’s AI agent

October 12, 2026
OpenAI Denies Firing Researchers Over AI Safety Warnings
Artificial Intelligence

OpenAI Denies Firing Researchers Over AI Safety Warnings

October 12, 2026
France’s Mistral introduces latest model in sovereign AI push
Artificial Intelligence

France’s Mistral introduces latest model in sovereign AI push

October 8, 2026
AI behaves more like a brain than a database—cognitive science’s role in its origin story supports explain why
Artificial Intelligence

AI behaves more like a brain than a database—cognitive science’s role in its origin story supports explain why

October 8, 2026
Next Post
NVIDIA recent: Blackwell GPU and software updates

NVIDIA recent: Blackwell GPU and software updates

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

− 1 = 1

TRENDING

How blockchain is arising as the best bid for small businesses?

How-blockchain-is-arising-as-the-best-bid-for-small-businesses
by Manika Sharma
May 17, 2021
0
ShareTweetShareSend

MIT’s Optical AI Chip That Could Revolutionize 6G at the Speed of Light

MIT’s Optical AI Chip That Could Revolutionize 6G at the Speed of Light

Photo Credit: https://scitechdaily.com/

by Tarun Khanna
June 23, 2025
0
ShareTweetShareSend

Databricks co-founder claims US must go open source to beat China in AI

Databricks co-founder claims US must go open source to beat China in AI

Photo Credit: https://techcrunch.com/

by Tarun Khanna
November 16, 2025
0
ShareTweetShareSend

The OpenAI Files: Ex-staff claim profit greed betraying AI protection

The OpenAI Files: Ex-staff claim profit greed betraying AI protection

Photo Credit: https://www.artificialintelligence-news.com/

by Tarun Khanna
June 23, 2025
0
ShareTweetShareSend

AI Isn’t a Bubble however a Long-Term Opportunity, JPMorgan’s Erdoes stated

AI Isn’t a Bubble however a Long-Term Opportunity, JPMorgan’s Erdoes stated

Photo Credit: https://opendatascience.com/

by Tarun Khanna
November 16, 2025
0
ShareTweetShareSend

Benefits of Hardware as a Service for Companies

Hardware as a Service
by Tarun Khanna
June 18, 2024
0
ShareTweetShareSend

DeepTech Bytes

Deep Tech Bytes is a global standard digital zine that brings multiple facets of deep technology including Artificial Intelligence (AI), Machine Learning (ML), Data Science, Blockchain, Robotics,Python, Big Data, Deep Learning and more.
Deep Tech Bytes on Google News

Quick Links

  • Home
  • Affiliate Programs
  • About Us
  • Write For Us
  • Submit Startup Story
  • Advertise With Us
  • Terms of Service
  • Disclaimer
  • Cookies Policy
  • Privacy Policy
  • DMCA
  • Contact Us

Topics

  • Artificial Intelligence
  • Data Science
  • Python
  • Machine Learning
  • Deep Learning
  • Big Data
  • Blockchain
  • Tableau
  • Cryptocurrency
  • NFT
  • Technology
  • News
  • Startups
  • Books
  • Interview Questions

Connect

For PR Agencies & Content Writers:

connect@deeptechbytes.com

Facebook Twitter Linkedin Instagram
Listen on Apple Podcasts
Listen on Google Podcasts
DMCA.com Protection Status

© 2024 Designed by AK Network Solutions

Welcome Back!

Login to your account below

Forgotten Password?

Retrieve your password

Please enter your username or email address to reset your password.

Log In
No Result
View All Result
  • Artificial Intelligence
  • Data Science
    • Language R
    • Deep Learning
    • Tableau
  • Machine Learning
  • Python
  • Blockchain
  • Crypto
  • Big Data
  • NFT
  • Technology
  • Interview Questions
  • Others
    • News
    • Startups
    • Books

© 2023. Designed by AK Network Solutions