On this page
- Key takeaways
- What did AWS announce for SageMaker?
- What is SageMaker Data Wrangler?
- What does SageMaker Feature Store do?
- What are SageMaker Pipelines?
- Why does SageMaker Clarify matter?
- How do Deep Profiling and Distributed Training speed up training?
- What is SageMaker Edge Manager?
- What is SageMaker JumpStart?
- Frequently asked questions
- Conclusion
Amazon Web Services (AWS) announced nine major updates to Amazon SageMaker, its cloud-based machine learning platform, at its re:Invent conference in late 2020. The updates cover data preparation, feature storage, pipelines, bias detection, training performance, edge deployment and beginner onboarding.
SageMaker is designed as a service for building, training and deploying machine learning (ML) models for virtually any use case. This article summarizes each announcement as described at the time.
Key takeaways
- AWS announced nine SageMaker updates: Data Wrangler, Feature Store, Pipelines, Clarify, Deep Profiling, Distributed Training, Data Parallelism, Edge Manager and JumpStart.
- Together they target the full ML workflow, from preparing data to monitoring models after deployment.
- Several performance figures, such as faster training and single-digit millisecond latency, were AWS claims rather than independent results.
- AWS said it had delivered more than 50 new SageMaker capabilities over the past year.
What did AWS announce for SageMaker?
Swami Sivasubramanian, VP of Amazon Machine Learning at AWS, said hundreds of thousands of developers and data scientists had used SageMaker to build, train and deploy custom models. He said customer suggestions fuel each new set of features. The new tools aim to help developers build end-to-end ML pipelines that prepare, build, train, explain, inspect, monitor, debug and run models with more visibility, explainability and automation at scale.
| Announcement | What it is meant to do |
|---|---|
| Data Wrangler | Automates data preparation for machine learning |
| Feature Store | A repository to store, update, retrieve and share ML features |
| Pipelines | CI/CD service for machine learning workflows |
| Clarify | Detects bias across the ML workflow |
| Deep Profiling | Monitors resource use and flags training bottlenecks |
| Distributed Training | Trains large deep learning models faster |
| Data Parallelism engine | Splits training data across many GPUs |
| Edge Manager | Manages models on fleets of edge devices |
| JumpStart | Helps beginners get started with ready-made templates |
What is SageMaker Data Wrangler?
Data Wrangler aims to automate the preparation of data for machine learning. Customers choose the data they want from their various data stores and import it with a single click. More than 300 built-in data transformers help normalize, transform and combine features without writing code.
Frank Farrall, Principal of AI Ecosystems and Platforms Leader at Deloitte, said the tool gave his team a quick start on data preparation and helped deliver results for clients in days rather than months.
What does SageMaker Feature Store do?
Feature Store is a repository that makes it easy to store, update, retrieve and share ML features for training and inference. It targets the problem of managing features that are used by multiple models. A purpose-built store makes it easier to name, organize, find and share feature sets among teams of developers and data scientists.
Because it resides in SageMaker Studio, close to where models run, AWS claims it provides single-digit millisecond inference latency. Mammad Zadeh, VP of Engineering, Data Platform at Intuit, said a fully managed feature store means his company no longer has to maintain multiple feature repositories, and that data scientists can reuse features across teams and models.
What are SageMaker Pipelines?
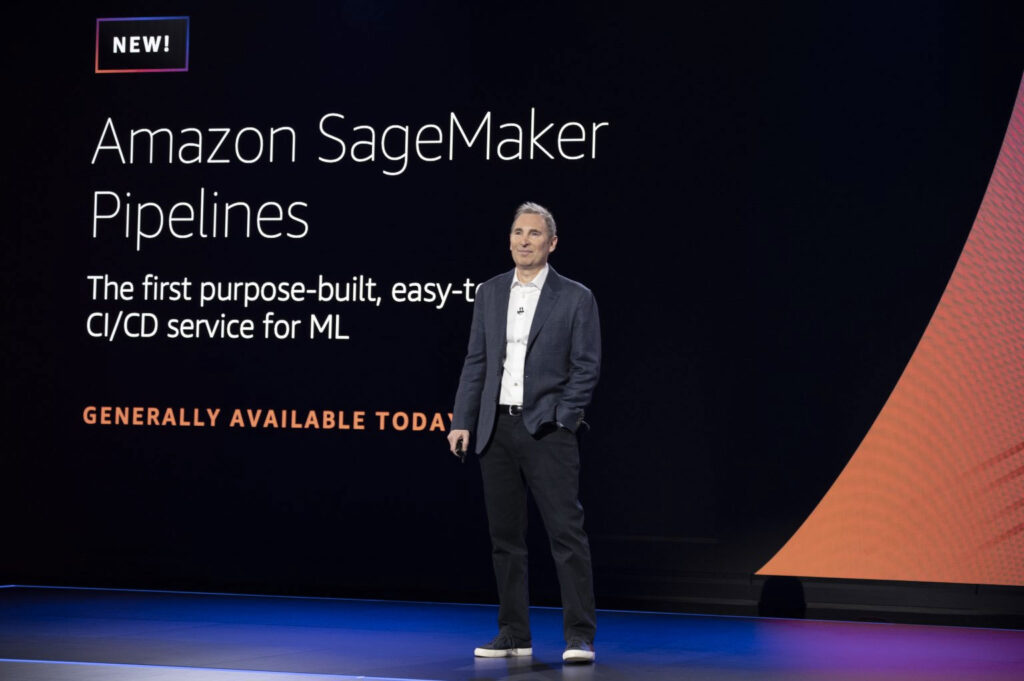
SageMaker Pipelines claims to be the first purpose-built, easy-to-use continuous integration and continuous delivery (CI/CD) service for machine learning. Developers can define each step of an end-to-end workflow. These steps include data loading, transformations from Data Wrangler, features from Feature Store, training configuration and algorithm setup, debugging and optimization.
Why does SageMaker Clarify matter?
Clarify aims to provide bias detection across the machine learning workflow, so developers can build more fairness and transparency into their models. Instead of turning to time-consuming open-source tools, developers can use an integrated solution to find and counter bias in models. The original coverage called it one of the most important features of the week, given the debate around AI at the time.
Andreas Heyden, Executive VP of Digital Innovations at the DFL Group, said Clarify integrates with the Bundesliga Match Facts platform and fits the group’s long-term plan to standardize its ML workflows on SageMaker.
How do Deep Profiling and Distributed Training speed up training?
Deep Profiling automatically monitors system resource use and sends alerts when it detects training bottlenecks. It works across PyTorch, Apache MXNet and TensorFlow, and collects system and training metrics without code changes to training scripts.
Distributed Training on SageMaker, according to AWS, makes it possible to train large, complex deep learning models up to two times faster than current approaches. Its Data Parallelism engine scales training jobs from a single GPU to hundreds or thousands by automatically splitting data across GPUs, improving training time by up to 40 percent.
Kristóf Szalay, CTO at Turbine, said his company trains a simulated human cell model to help discover cancer drugs. Each training run takes days on a single machine, and he expected Distributed Training to cut training times by 90%.
What is SageMaker Edge Manager?
Edge Manager helps developers optimize, secure, monitor and maintain ML models deployed on fleets of edge devices. It can cryptographically sign models and upload prediction data from devices to SageMaker for monitoring and analysis. A dashboard in the SageMaker console gives a visual report on how deployed models are performing.
Igor Bergman, VP of Cloud and Software of PCs and Smart Devices at Lenovo, said it should remove the manual work of optimizing and monitoring models after deployment, and that he expected models to run faster and use less memory than on comparable platforms.
What is SageMaker JumpStart?
JumpStart is meant to help developers with little ML deployment experience get started. It offers a searchable interface to find solutions, algorithms and sample notebooks. Developers can choose from end-to-end templates, such as fraud detection, customer churn prediction or forecasting, and deploy them directly into SageMaker Studio.
Frequently asked questions
When were these SageMaker updates announced?
They were announced during AWS re:Invent in late 2020, and this coverage was published in January 2021.
Do Data Wrangler and Feature Store require coding?
Data Wrangler includes more than 300 built-in transformers so common transformations need no code. Feature Store is a managed repository for sharing features between models and teams.
Are the performance numbers independently verified?
No. Figures such as the two-times training speedup and the single-digit millisecond latency were AWS claims at launch.
Which frameworks does Deep Profiling support?
It works across PyTorch, Apache MXNet and TensorFlow.
Conclusion
The nine announcements extended SageMaker across the whole ML lifecycle, from data preparation to edge deployment, with added attention to bias detection and training speed. AWS noted more than 50 new capabilities in the past year, and the details above reflect the platform as announced in 2020.